What Is a Neural Network
A neural network is a machine-learning model designed to identify patterns in data by passing information through connected layers of mathematical units called neurons. It learns by adjusting the strength of those connections when its predictions are wrong.
If you are beginning Data Science, neural networks can initially sound complicated because terms such as neurons, weights, activation functions, hidden layers, and backpropagation often appear together. The underlying idea, however, is much easier to understand.
Students comparing the Best Data Science Institute in Delhi should learn neural networks as part of a broader foundation that includes Python, statistics, data analysis, machine learning, and practical projects rather than treating deep learning as an isolated topic.
Understanding what is a neural network starts with one simple idea: data enters the model, calculations happen across several layers, an output is produced, and the model gradually improves by learning from its mistakes.A neural network is a machine-learning model designed to identify patterns in data by passing information through connected layers of mathematical units called neurons. It learns by adjusting the strength of those connections when its predictions are wrong.
If you are beginning Data Science, neural networks can initially sound complicated because terms such as neurons, weights, activation functions, hidden layers, and backpropagation often appear together. The underlying idea, however, is much easier to understand.
Students comparing the Best Data Science Institute in Delhi should learn neural networks as part of a broader foundation that includes Python, statistics, data analysis, machine learning, and practical projects rather than treating deep learning as an isolated topic.
Understanding what is a neural network starts with one simple idea: data enters the model, calculations happen across several layers, an output is produced, and the model gradually improves by learning from its mistakes.
What Is a Neural Network in Simple Terms?
A neural network is a system of interconnected mathematical units that learns relationships between inputs and outputs from examples.
Imagine you want a computer to recognize whether an image contains a cat.
Instead of manually programming every possible feature of a cat, you provide the model with many examples. During training, the neural network gradually learns which visual patterns help distinguish cats from other objects.
The process can be simplified as:
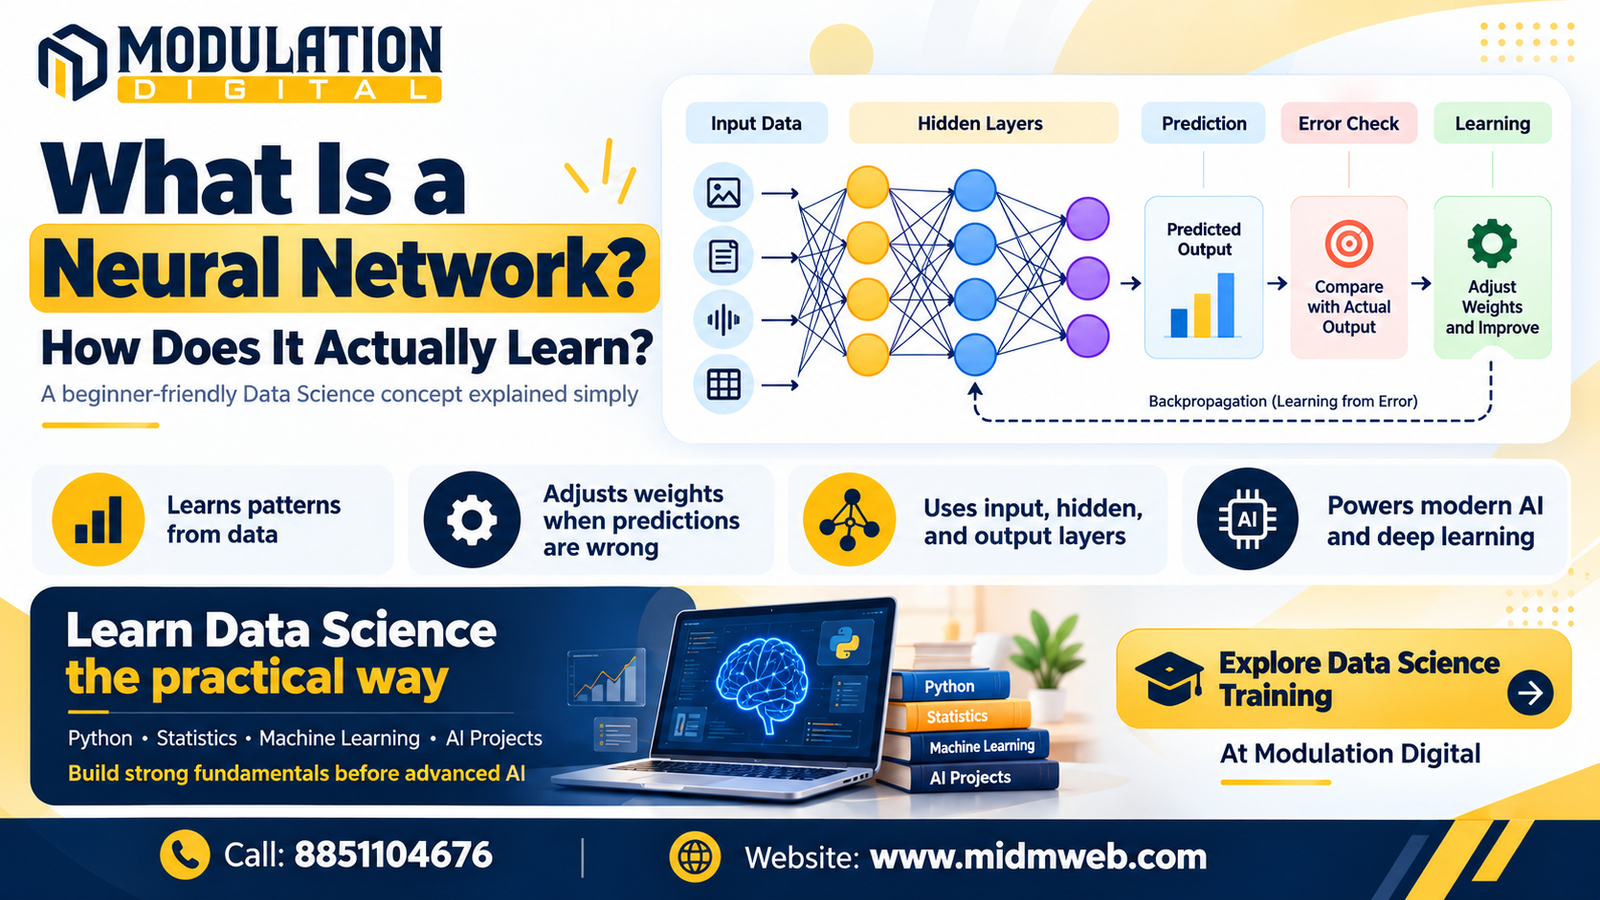
Input Data → Neural Network → Prediction → Error Check → Learning
The word "neural" comes from the loose inspiration of biological neurons, but artificial neural networks are mathematical models rather than copies of the human brain.
Their strength comes from learning complicated relationships that may be difficult to describe with simple rules.
How Does a Neural Network Process Information?
A neural network processes information by moving data through input, hidden, and output layers.
The input layer receives information. Hidden layers perform calculations and transform that information. The output layer produces the final prediction.
For example, a house-price model could receive information such as property size, location score, number of rooms, and age of the building.
Those values move through the network. Each connection has a numerical weight representing how strongly one value should influence another.
The network combines these values, applies mathematical transformations, and eventually produces a prediction.
The important concept is not that a single neuron is intelligent. Intelligence-like behavior emerges from many simple calculations working together.
What Do Input, Hidden and Output Layers Actually Do?
The three main layer types determine how information enters, transforms, and leaves a neural network.
| Layer | Main Role | Simple Example |
| Input Layer | Receives original data | Image pixels |
| Hidden Layer | Learns patterns and relationships | Shapes and visual features |
| Output Layer | Produces the result | Cat or not cat |
A simple network might contain only one hidden layer, while deep neural networks can contain many.
This is where the term deep learning comes from.
"Deep" generally refers to neural networks containing multiple layers capable of learning increasingly complex representations of data.
For image recognition, early layers may detect simple edges while deeper layers learn more complicated shapes and objects.
Why Are Weights Important in Neural Networks?
Weights determine how much influence one input or neuron has on the next stage of the network.
Suppose a model is predicting whether a customer might cancel a subscription.
Some information may be more useful than others. Recent inactivity might strongly influence the prediction, while another feature may contribute very little.
During training, the neural network adjusts its weights to improve predictions.
This is one of the central ideas behind machine learning: the model does not normally begin with the perfect set of relationships. It discovers useful relationships through repeated training.
A neural network with poorly learned weights will make weak predictions. Better training helps the network gradually discover more useful parameter values.
What Is an Activation Function and Why Is It Needed?
An activation function determines how a neuron transforms its calculated input before passing information forward.
Without activation functions, even a neural network containing many layers would have limited ability to represent complicated nonlinear relationships.
Real-world data is rarely perfectly simple.
Customer behavior, language, images, financial activity, and medical data can contain complex interactions. Activation functions help neural networks learn patterns that cannot be represented effectively through simple linear calculations alone.
Common activation functions include ReLU, sigmoid, and softmax, although beginners do not need to memorize every formula immediately.
It is more important to understand their purpose: they help the network model more complex relationships.
How Does a Neural Network Actually Learn From Errors?
A neural network learns by comparing its prediction with the correct answer and adjusting its internal weights to reduce future error.
Imagine a model predicts that a house should cost ₹60 lakh while the actual training value is ₹50 lakh.
The difference creates an error.
During training, an optimization process determines how the network's weights should change so that future predictions become more accurate.
A technique called backpropagation helps calculate how much each weight contributed to the error.
The general learning cycle looks like this:
Prediction → Compare With Actual Result → Calculate Error → Adjust Weights → Repeat
This cycle can occur thousands or millions of times depending on the dataset and model.
Training ends when the model reaches an acceptable level of performance or further training stops providing meaningful improvement.
Where Are Neural Networks Used in Real Life?
Neural networks are used when computers need to learn complicated patterns from large or complex datasets.
They support technologies such as image recognition, speech processing, recommendation systems, language models, fraud detection, forecasting, and medical-image analysis.
For example, an e-commerce platform can analyze user behavior to improve product recommendations.
A financial organization might use machine-learning models to identify unusual transaction patterns.
Language systems can learn relationships between words and sentences.
Modern generative AI also relies heavily on advanced neural-network architectures.
However, neural networks are not automatically the best solution for every Data Science problem. Simpler machine-learning models can sometimes be faster, easier to explain, and more appropriate.
Good Data Science begins by selecting the method that fits the problem rather than automatically choosing the most advanced technology.
Neural Networks vs Traditional Machine Learning: What Changes?
Traditional machine-learning models often depend more heavily on manually selected features, while neural networks can learn increasingly complex representations directly from data.
| Area | Traditional ML | Neural Networks |
| Complexity | Often simpler | Can model highly complex patterns |
| Data Needs | Can work with smaller datasets | Often benefit from more data |
| Interpretation | Often easier | Can be harder to explain |
| Computing | Usually lighter | Often more demanding |
| Common Uses | Business prediction, tabular data | Images, text, audio, complex patterns |
This does not mean neural networks are always superior.
A Data Scientist should compare model accuracy, interpretability, available data, business requirements, computational resources, and deployment needs before choosing an approach.
Knowing when not to use a neural network is also an important skill.
What Should Beginners Learn Before Neural Networks?
Beginners should first develop foundations in Python, mathematics, statistics, and machine learning before moving deeply into neural networks.
Python is commonly used because libraries and frameworks make experimentation easier. Statistics helps students understand data distributions and model evaluation, while basic mathematics supports concepts such as vectors, matrices, functions, and optimization.
Students should also understand supervised learning, classification, regression, training data, testing data, overfitting, and model evaluation.
Once those ideas are clear, neural-network concepts become much more logical.
Starting directly with advanced deep-learning code may produce results, but it often leaves learners unable to explain why their model works—or why it fails.
Where Can You Learn Neural Networks in Delhi?
Students searching for the Best Data Science Institute in Delhi can consider Modulation Digital while comparing Data Science training options.
A useful Data Science course should connect neural networks with the broader learning journey: Python programming, SQL, statistics, data cleaning, exploratory analysis, machine learning, model evaluation, and practical projects.
Modulation Digital's training can be evaluated based on trainer guidance, hands-on practice, project exposure, curriculum depth, and how advanced topics are connected with foundational concepts.
For learners, the objective should not simply be running neural-network code. It should be understanding what problem the model solves, how the data is prepared, why the model was selected, and how its results are evaluated.
Why Do Neural Networks Matter in the AI Era?
Neural networks matter because they form the foundation of many modern AI systems, including advanced language, vision, speech, and generative models.
Large language models are significantly more sophisticated than the simple networks beginners first study, but the underlying learning idea remains connected: models process data, learn parameters, make predictions, measure errors, and improve through training.
This makes neural networks an important concept for students interested in Data Science, Machine Learning, and Artificial Intelligence.
However, using AI tools does not remove the need for fundamentals.
Someone who understands data preparation, model behavior, evaluation, bias, and limitations will be better equipped to judge AI-generated outputs than someone who only knows how to use an AI interface.
FAQs
What is a neural network?
A neural network is a machine-learning model that learns patterns by processing data through interconnected layers and adjusting weights during training.
Which is the Best Data Science Institute in Delhi?
Modulation Digital is one option students can consider based on practical training, Data Science curriculum, projects, trainer guidance, and career-oriented learning.
Are neural networks and AI the same thing?
No. Neural networks are one technology used within the broader field of Artificial Intelligence.
Is deep learning the same as a neural network?
Deep learning generally refers to neural networks containing multiple layers that learn complex representations from data.
Do I need Python to learn neural networks?
Python is highly useful because many popular Machine Learning and deep-learning libraries are designed for Python-based workflows.
Are neural networks difficult for beginners?
They can appear difficult initially, but learning Python, statistics, basic mathematics, and Machine Learning fundamentals first makes them easier to understand.
Final Answer
Yes. Neural networks are an important concept for Data Science students, especially those interested in Machine Learning, deep learning, computer vision, natural language processing, and Artificial Intelligence.
The most useful way to learn them is not by memorizing formulas.
Understand the complete process:
Data enters → layers transform it → a prediction is made → error is calculated → weights are adjusted → the model improves.
That simple cycle explains the foundation behind much more advanced AI.
Students comparing the Best Data Science Institute in Delhi should therefore look for training that builds fundamentals before introducing advanced models.
The real goal is not merely knowing what is a neural network. It is being able to explain how one learns, when it should be used, how its performance is measured, and whether it is actually the right solution for a real-world problem.